You press the button, but the game registers the action after your opponent has already moved. On a video call, someone finishes a sentence and the audio arrives in broken pieces, forcing both people to pause and guess who should speak. The connection may have plenty of bandwidth, yet the experience still feels slow.
That difference comes from latency, not just internet speed. Edge computing low latency aims to shorten the distance between a person or device and the application responding to it. Fiber provides a consistent physical path, while managed edge services can place selected workloads closer to users. The result isn't automatically perfect, but it can make the difference between a smooth interaction and one that feels delayed.
Why a Few Milliseconds Change Everything
Latency is the delay between an action and the response it produces. In a game, that means the time between pressing a key and seeing movement or receiving hit confirmation. In a call, it means the time between speaking and the other person hearing you.
Bandwidth answers a different question. It describes how much data a connection can carry. Latency describes how quickly a particular piece of data begins and completes its journey. A large pipe doesn't guarantee a short trip, just as a wide highway doesn't guarantee that a driver will reach the destination quickly if the route includes long detours and traffic queues.
A useful analogy is driving. A sports car with a high top speed won't help much if it has to travel through a distant city, stop at several toll booths, and wait behind congestion. A shorter route with predictable traffic often produces the faster arrival. Networks work similarly. The application, route, queues, and distance all affect the time between cause and effect.
Why interactive applications notice delay
A gap of 30 to 50 milliseconds can determine whether a competitive player's action registers before an opponent reaches cover, or whether the result appears late. That range is provided in the brief as an example of an interactive difference, not as a universal performance threshold. The exact experience depends on the game engine, device, connection, and server location.
Conversation exposes latency in a different way. A small delay can make people interrupt each other, while a larger delay creates the unnatural pauses associated with long-distance broadcast conversations. Voice systems also suffer when packet arrival times vary, because they must buffer or reconstruct audio rather than playing each syllable at a steady pace.
Practical rule: For interactive services, the question isn't only “How much data can the network carry?” It's “How quickly and consistently can the application respond?”
The central engineering problem is therefore simple to state: how can the network reduce the path between user and application, then keep the slowest responses from becoming disruptive?
What Edge Computing and Latency Mean
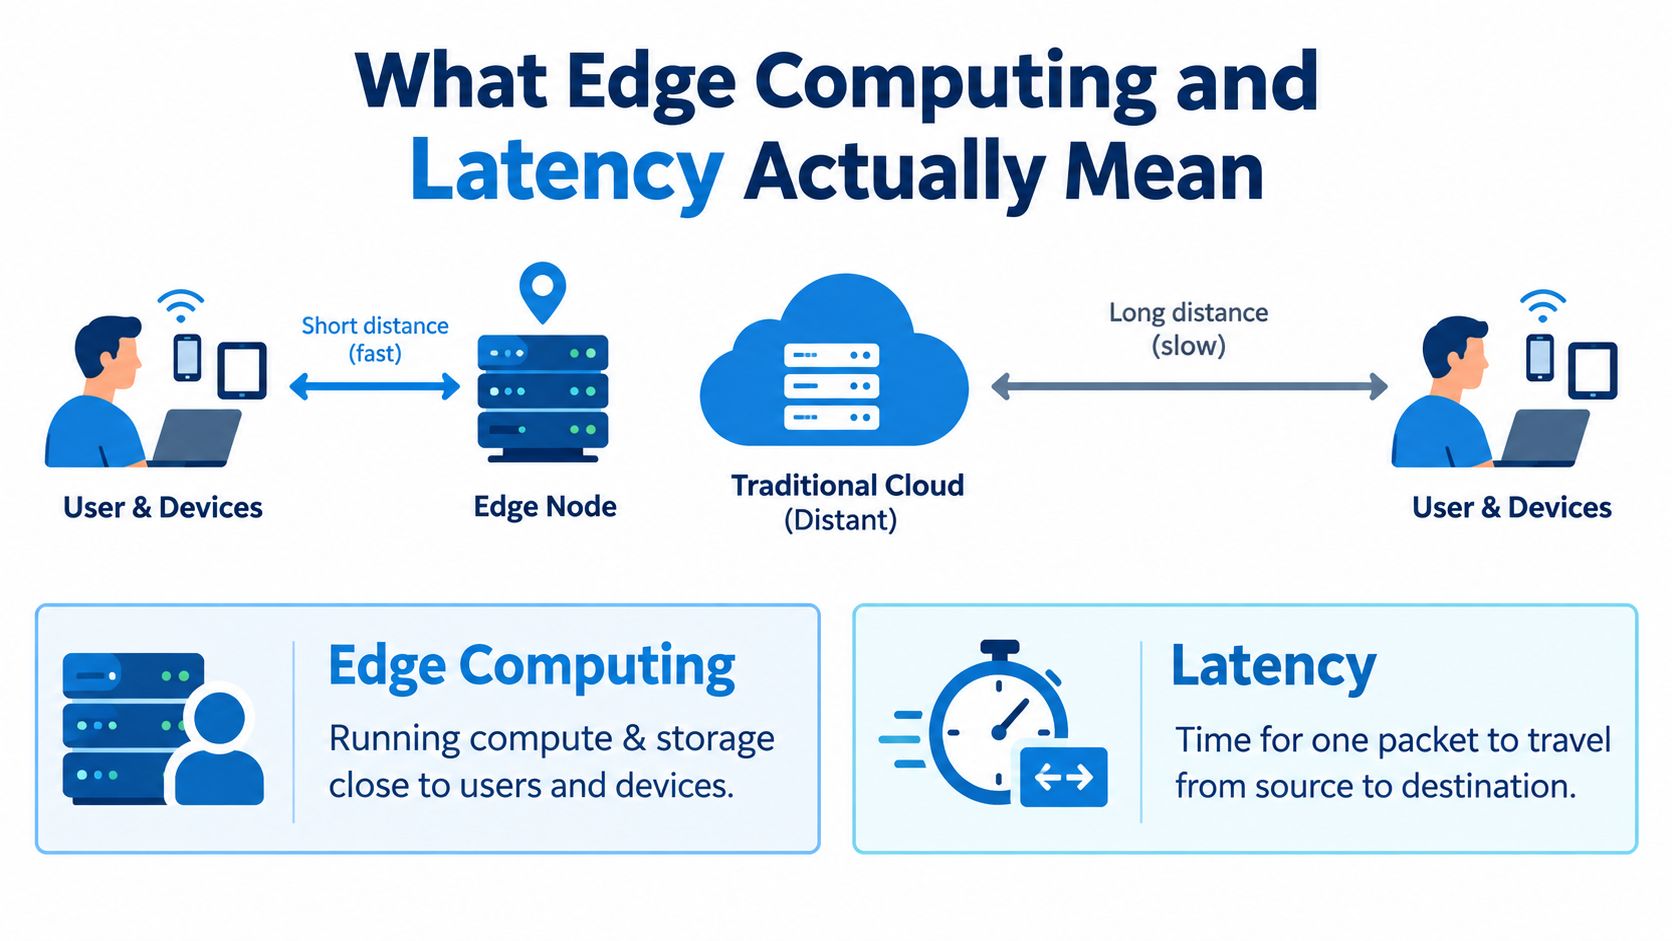
A gamer presses a button, a sensor detects a change, or someone speaks during a call. The useful response depends on how quickly that request reaches the application and how consistently the reply returns. Edge computing changes that route by placing processing and storage near the people, devices, or machines generating requests.
Instead of sending every interaction to a distant centralized cloud region, an organization can run selected services on a nearby edge node, gateway, or localized data center. The edge is not automatically faster for every workload. Its advantage appears when a shorter, more predictable path helps an application stay below a response threshold.
Latency is the time data needs to travel through a network. Engineers distinguish one-way latency from round-trip time, or RTT. RTT includes the journey to the service and the return journey to the user, so an application that sends a command and waits for confirmation depends on the full exchange.
Distance sets a physical limit. Light travels more slowly through fiber than through a vacuum, and a distant application begins with a longer possible route. Routers, queues, traffic handoffs, encryption, processing, and return traffic add further delay. Congestion can also make the slowest responses much later than the usual ones, creating jitter that a game, call, or video session exposes.
One path, two architectures
A sensor or gamer sending traffic to a cloud-only application may cross the access network, an aggregation point, an interconnection, and several more links before reaching a centralized region. The response then travels along a related route.
With an edge design, local breakout can direct the request to a nearby edge service. The path is shorter geographically and logically, giving packets fewer opportunities to encounter queues or congested handoffs.
A 2021 networking study found that 58% of end users could reach a nearby edge server in under 10 ms, compared with 29% who could reach a nearby cloud location at that same speed (the published networking study). It also reported edge placement improvements of 6% to 30% over actual cloud access latency, with some horizontal paths reaching up to 40%. The absolute reduction was often around 2 ms (the study's measurement results).
These results define the practical boundary. Edge computing cannot change the speed of light, repair a poor access link, or remove delay inside an overloaded device. Fiber provides the physical path, while managed edge placement helps keep that path short and controlled. Together, they can reduce average delay and limit the tail responses that make an otherwise fast session feel uneven.
The Metrics That Decide If a Connection Feels Fast
An average latency figure can hide the event users remember. A call may sound clear for most of its duration, then freeze during one important sentence. A game may respond instantly for several minutes, then stall during a decisive exchange. Engineers need more than one number to understand those failures.
Jitter measures variation in packet arrival timing. If packets arrive evenly, a voice or video application can play them smoothly. If one packet arrives quickly and the next arrives much later, the application may stretch its buffer, produce robotic audio, or display a frozen frame.
Tail latency describes the slower portion of responses rather than the typical response. A p99 measurement represents the boundary below which 99% of observed responses fall, leaving the slowest 1 in 100 responses above it. For a game, those occasional slow responses may appear as a freeze. For a call, they may create a clipped word or a visible pause.
Packet loss occurs when packets don't reach their destination. Applications may conceal a small loss by using redundancy or interpolation, but missing data can also trigger retransmissions. Those retries add delay and can create bursts of traffic precisely when the network is already under pressure.
A practical metric comparison
The table uses qualitative thresholds rather than invented universal targets. “Good” depends on the application, codec, protocol, device, and user tolerance.
| Metric | What It Measures | Typical Good Threshold | What Breaks When It Spikes |
|---|---|---|---|
| Latency | Time for traffic to travel between endpoints | Low enough to stay within the application's response limit | Inputs feel delayed, conversations develop pauses, control loops react late |
| Jitter | Variation in packet arrival times | Stable and predictable delivery | Voice becomes choppy, video stutters, game movement appears uneven |
| p99 latency | Slow-tail response behavior | A tail that remains near the normal response range | Occasional freezes, delayed actions, and sudden interface stalls |
| Packet loss | Traffic that never arrives | Minimal loss for the application's tolerance | Retransmissions, missing audio, corrupted frames, or dropped updates |
A simple example shows why averages mislead. A connection with 20 ms average latency, 5 ms jitter, and a 400 ms p99 might feel fine most of the time, yet that long-tail event can still cause the frozen frame that interrupts a sentence. Those values are illustrative, not a benchmark or recommended target.
For a deeper operational treatment of diagnosing combined delay and packet loss, the guide on stress test latency issues offers a useful troubleshooting resource. The main lesson is straightforward: measure the distribution, not just the average.
Where Low Latency Shows Up in Real Life
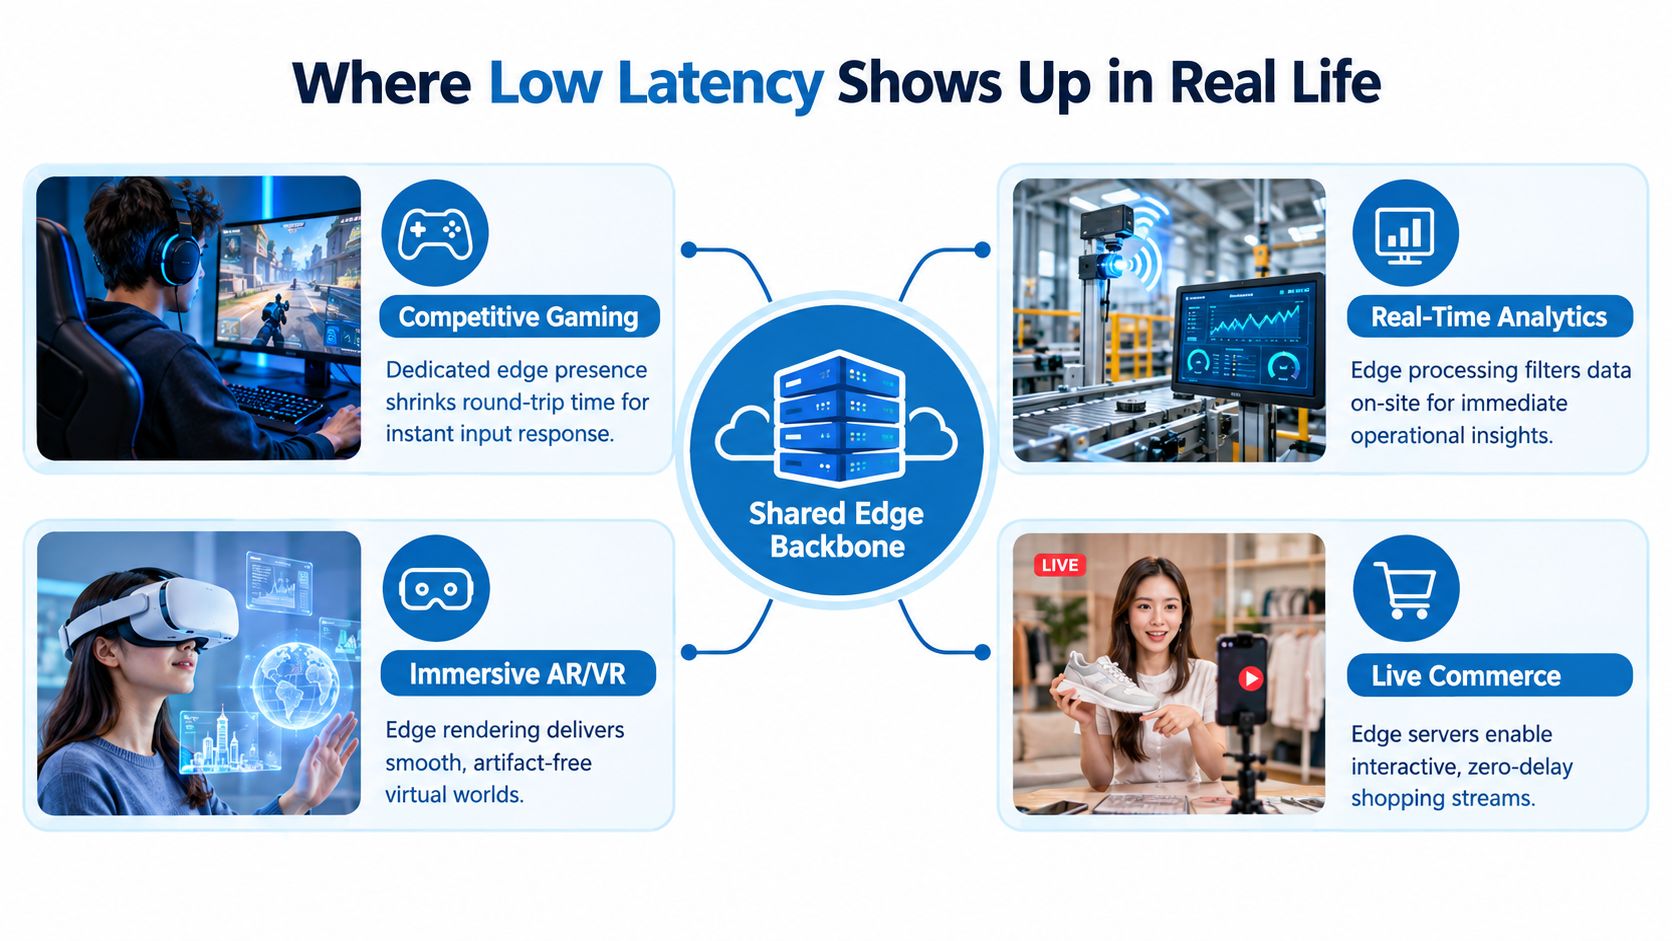
A player presses a button, a caller finishes a sentence, or a machine detects a pressure change. In each case, the experience depends on more than average latency. Tail latency, jitter, and packet loss determine whether the response arrives consistently or whether one delayed event disrupts the session.
Competitive gaming
A game server near its players shortens the round trip for movement, firing, state updates, and hit confirmation. Consistent delivery also keeps player positions synchronized, reducing the chance that one late update makes a valid action appear ineffective.
The difference is easiest to feel at the tail. A connection can report a low average while occasional spikes delay a shot, freeze a frame, or make another player appear to jump across the screen. Fiber provides a stable access path, while managed edge placement can keep the game workload closer to the players. Together, they address both distance and unpredictable queues.
Voice over IP
VoIP divides speech into packets and sends them to a media service or another endpoint. A nearby media relay reduces the distance those packets travel, while stable routing limits the variation between arrivals. The playback buffer can then preserve natural timing without waiting excessively for late packets.
A low average does not guarantee a natural call. A short burst of jitter or packet loss can clip syllables, create robotic audio, or cause participants to speak over one another. Call quality depends on whether these interruptions stay within the application's tolerance, not only on the usual round-trip result.
Video conferencing
Meetings combine several real-time streams. Microphones carry speech, cameras send moving images, screen sharing sends visual updates, and collaboration tools exchange reactions or captions. Regional relays and edge-hosted processing keep those streams closer to participants, helping responses arrive at a conversational pace.
Users do not inspect individual packets. They notice whether a colleague's reply arrives naturally, whether a shared screen changes promptly, and whether a brief disturbance becomes a recoverable pause or a disruptive freeze. Tail latency matters here because one slow stream can interrupt an otherwise smooth meeting.
Industrial IoT
A sensor may generate more information than a central cloud needs immediately. An edge gateway can inspect the local stream, identify abnormal vibration or pressure, and forward the relevant event for broader analysis. The immediate control loop remains local, while the cloud handles historical reporting, model training, and comparisons across sites.
Research has reported 60% to 70% reductions in end-to-end latency in an edge-based multi-algorithm system without sacrificing accuracy (the computer science research source). The exact gain depends on the workload and architecture. The practical rule is clear: local processing matters when a delayed response changes a physical process or interactive outcome.
Designing a Network for Low Latency
Low latency begins with placement, but placement alone doesn't create a predictable service. A network engineer evaluates the route from the user or device to the workload, then removes unnecessary distance, handoffs, and queues.
Start with local breakout
Local breakout sends traffic toward the closest suitable edge point rather than forcing it through a distant central hub. This choice can remove a geographic detour and keep interactive traffic within a regional path. It also makes measurement more meaningful because engineers can compare the user's access route, edge route, and application response separately.
The edge node must host the right work. Moving a service that still depends on a remote database, authorization system, or content origin may leave the slowest part of the transaction unchanged. Engineers therefore map dependencies before relocating a workload.
Choose the handoffs carefully
Peering and interconnection determine where one network hands traffic to another. A short, well-managed path can avoid unnecessary transit and reduce the queues introduced by congested public routes. This doesn't mean every private path is automatically faster. Teams still need to monitor loss, jitter, failover behavior, and the application's tail latency.
A symmetrical fiber circuit provides a stable foundation for this design because upload and download capacity are balanced, which matters when an application sends and receives traffic at the same time. The access link still needs clean optics, suitable routing, and consistent service. An edge node can't compensate for instability between the user and the provider.
Place only the urgent work
Keep latency-sensitive functions near the user or device. Examples include media relay, local control decisions, frequently accessed application state, and real-time inference. Leave bulk storage, long-running analytics, and broad historical processing in the core when those functions don't sit inside the interactive loop.
Engineering test: Trace one complete transaction from input to response. If any required dependency remains distant, moving only the front end to the edge may produce less improvement than expected.
Cloud, Edge, and Hybrid Compared
The best architecture depends on what the workload must do at the moment a user or machine sends a request. Three models make the tradeoff visible.
| Workload Trait | Edge-Only | Cloud-Only | Hybrid |
|---|---|---|---|
| Immediate response | Strong for local interactions | Weaker when the route is long | Strong when urgent functions stay local |
| Heavy computation | Limited by local capacity | Strong centralized capacity | Uses cloud capacity for intensive tasks |
| Large datasets | Awkward to replicate everywhere | Efficient for central storage | Stores centrally while caching or filtering locally |
| Local resilience | Can continue selected local tasks | Depends heavily on central reachability | Keeps critical paths local with central coordination |
| Global coordination | More complex across sites | Simple centralized control | Assigns coordination to the core and execution to the edge |
| Operations | Many distributed nodes to manage | Centralized management | More moving parts, with clearer workload separation |
Edge-only suits an isolated control loop or local service that must continue operating near its source. It becomes harder to manage when the application requires large models, broad historical data, or coordination across many regions.
Cloud-only offers centralized management and elastic resources. It remains a sensible choice for storage, training, reporting, and workloads whose users can tolerate a longer route. It becomes less suitable when every interaction depends on a distant round trip.
Hybrid keeps the urgent path close and sends non-urgent work to the core. Matchmaking decisions, media relays, command arbitration, or local filtering can run at the edge, while training, analytics, and archival storage remain centralized. A practical overview of coordinating these responsibilities appears in Server Scheduler hybrid cloud operations.
For organizations evaluating this model, Premier Broadband's Managed Network Edge can fit the network layer that connects distributed services, while its fiber service supplies the access path. The useful question isn't whether edge or cloud sounds more modern. It's which part of the workload must respond immediately and which part benefits from central scale.
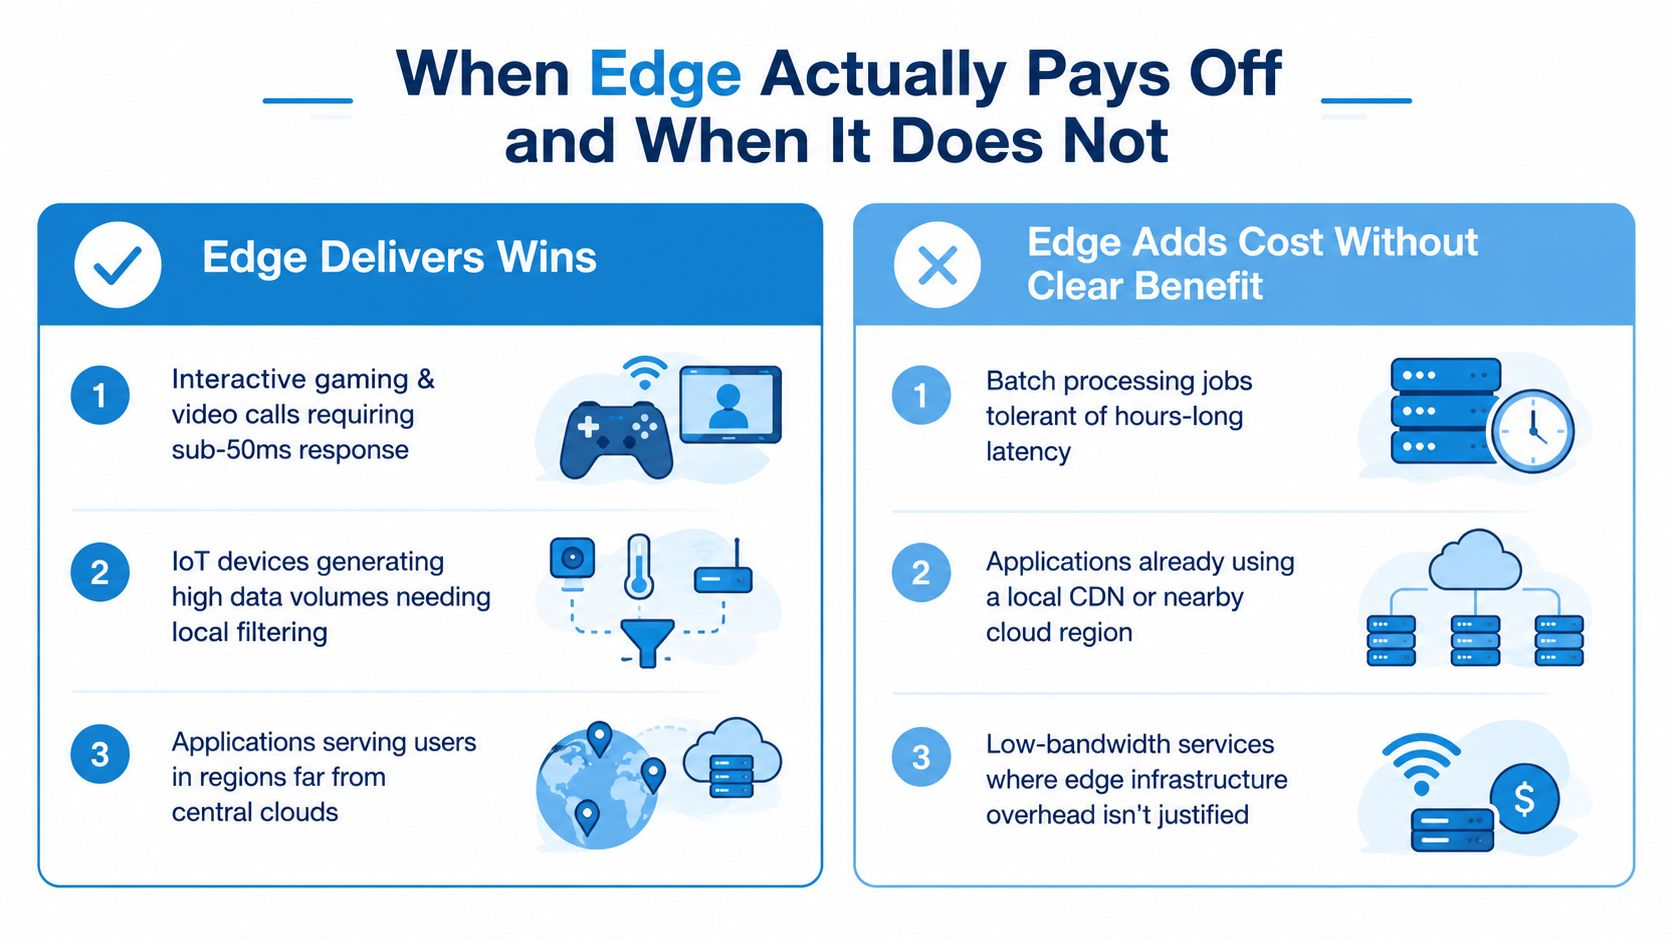
When Edge Pays Off and When It Does Not
Edge computing suits workloads where delay changes a user's action or a machine's state. It also adds infrastructure, software distribution, monitoring, security, and operational work. For an asynchronous task, that overhead may deliver no visible benefit.
Strong candidates for edge placement
Competitive multiplayer gaming is a clear candidate. Input, state synchronization, and hit confirmation form one interactive loop, so a long round trip or a wide spread in response times can make play feel uneven. Voice and video collaboration can benefit when a nearby relay shortens the path and steadies packet delivery. Industrial control and telematic IoT deserve consideration when a local decision must occur before a machine, vehicle, or process changes state.
A head-tracking measurement study found up to 19% latency reduction at the 80th percentile, with more than 80% of North American probes below the examined 20 ms threshold (the IFIP measurement study). The broader lesson is more useful than the average alone. Edge placement can help an application cross a practical response threshold or reduce tail latency and jitter, rather than merely lowering a number users cannot feel.
Poor candidates for unnecessary edge
Email synchronization, overnight backups, large file replication, and pre-rendered video delivery usually depend more on throughput, storage, scheduling, and cache behavior than on a small change in round-trip time. A local edge node can add deployment overhead without improving the part of the service users notice.
A review of edge deployment challenges identifies tradeoffs involving scheduling, reliability, energy use, benchmarking, hardware reliability, and orchestration (the review of edge deployment challenges). Edge placement is therefore a workload-specific choice, not a guarantee that every application responds faster.
Use this filter before investing:
- Go: The workload has a hard response threshold, sensitive packets, geographically distributed users, and enough operational value to justify local infrastructure.
- Evaluate: The application has interactive paths, but a nearby cloud region, CDN, or routing change may improve tail behavior with less operational work.
- Skip: The workload is batch-oriented, tolerates delay, or already sits near its users, and edge placement does not improve measured latency or jitter.
Putting It Together for Your Own Setup
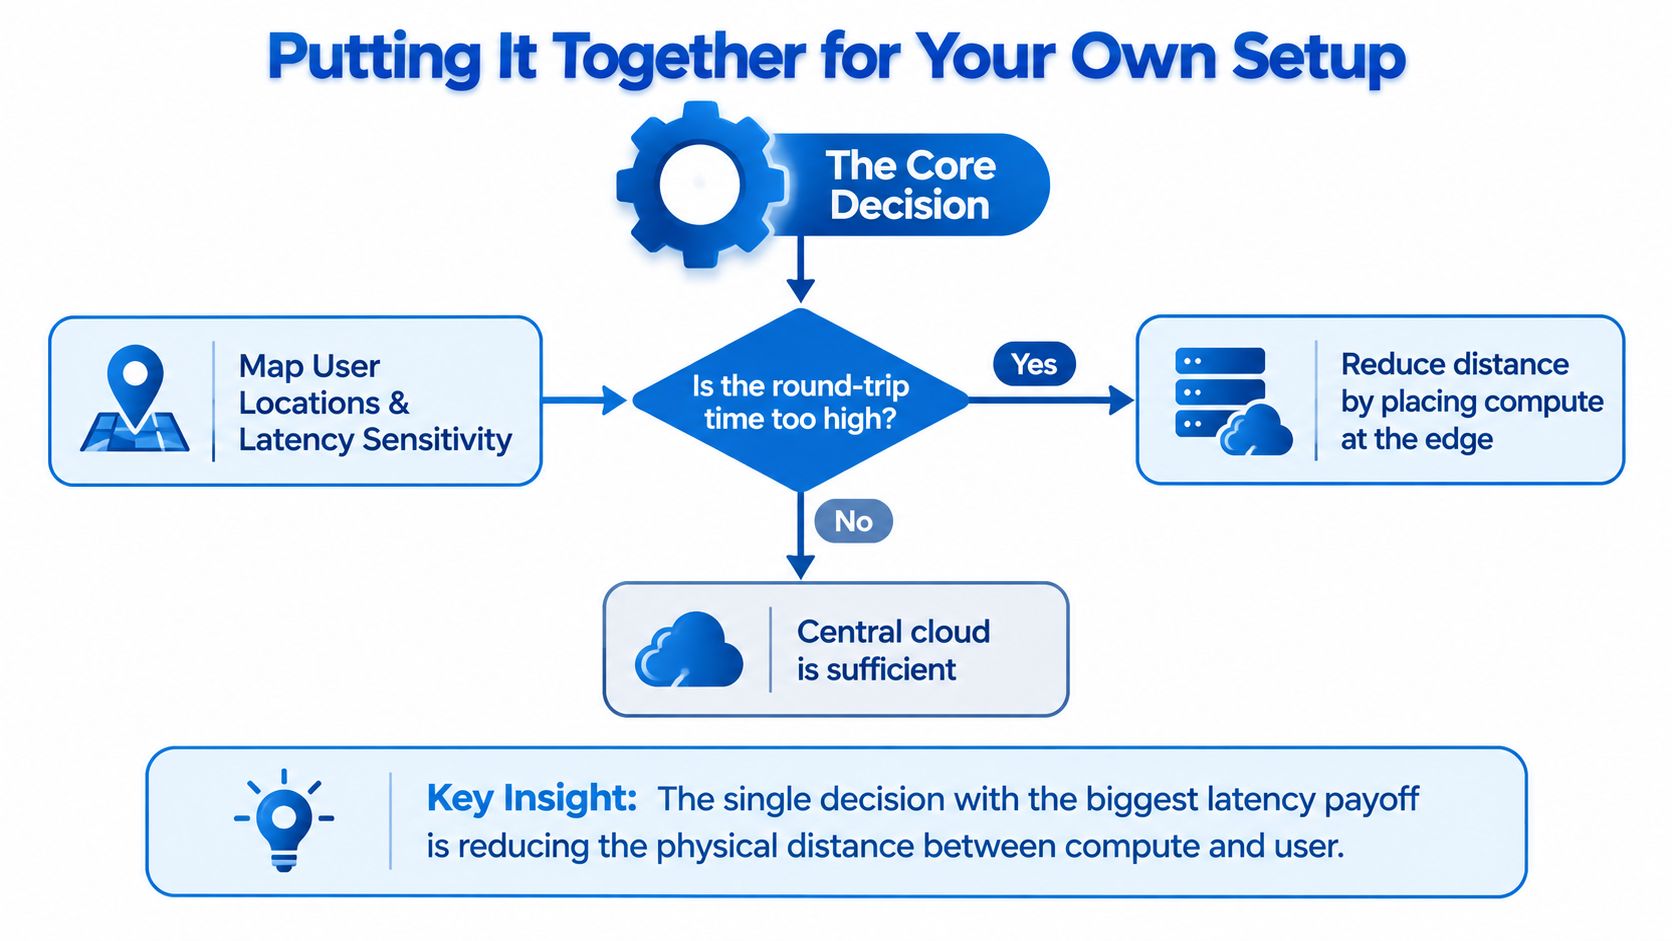
Start with the physical map. List where users, sensors, gateways, and applications live, then identify which interactions need an immediate response. The largest latency payoff usually comes from reducing the distance between the user and the workload, not from adding capacity to a distant server.
Next, inspect the access path. A consistent fiber link can reduce the variability introduced by the last mile, while a managed edge node or on-premises gateway can provide local breakout for selected traffic. Peering arrangements then determine whether that traffic takes a direct regional route or travels through avoidable public-network detours.
Measure the complete experience
Don't stop at a speed test. For gaming, record input response, packet loss, jitter, and p99 behavior while the service is under realistic load. For VoIP and conferencing, inspect audio interruptions, video freezes, and tail response during simultaneous uploads. For IoT, measure the full sensor-to-decision-to-confirmation loop.
The measurements should guide placement. If the slow tail appears between the user and the access network, changing application location won't fix it. If the access path is stable but the application sits far away, edge placement becomes more relevant. If the application depends on a distant database, redesigning that dependency may matter more than moving the interface.
Premier Broadband offers 100% fiber connectivity with symmetrical upload and download speeds, business VoIP, and Managed Network Edge services for organizations that need a managed network foundation for distributed operations. Visit Premier Broadband to discuss a fiber and edge approach built around your users, workload dependencies, and measured latency requirements.